Your team wants to use Claude on contracts, customer records or internal documents. The question is no longer only whether the model is capable enough. It is also where does the request actually get processed?
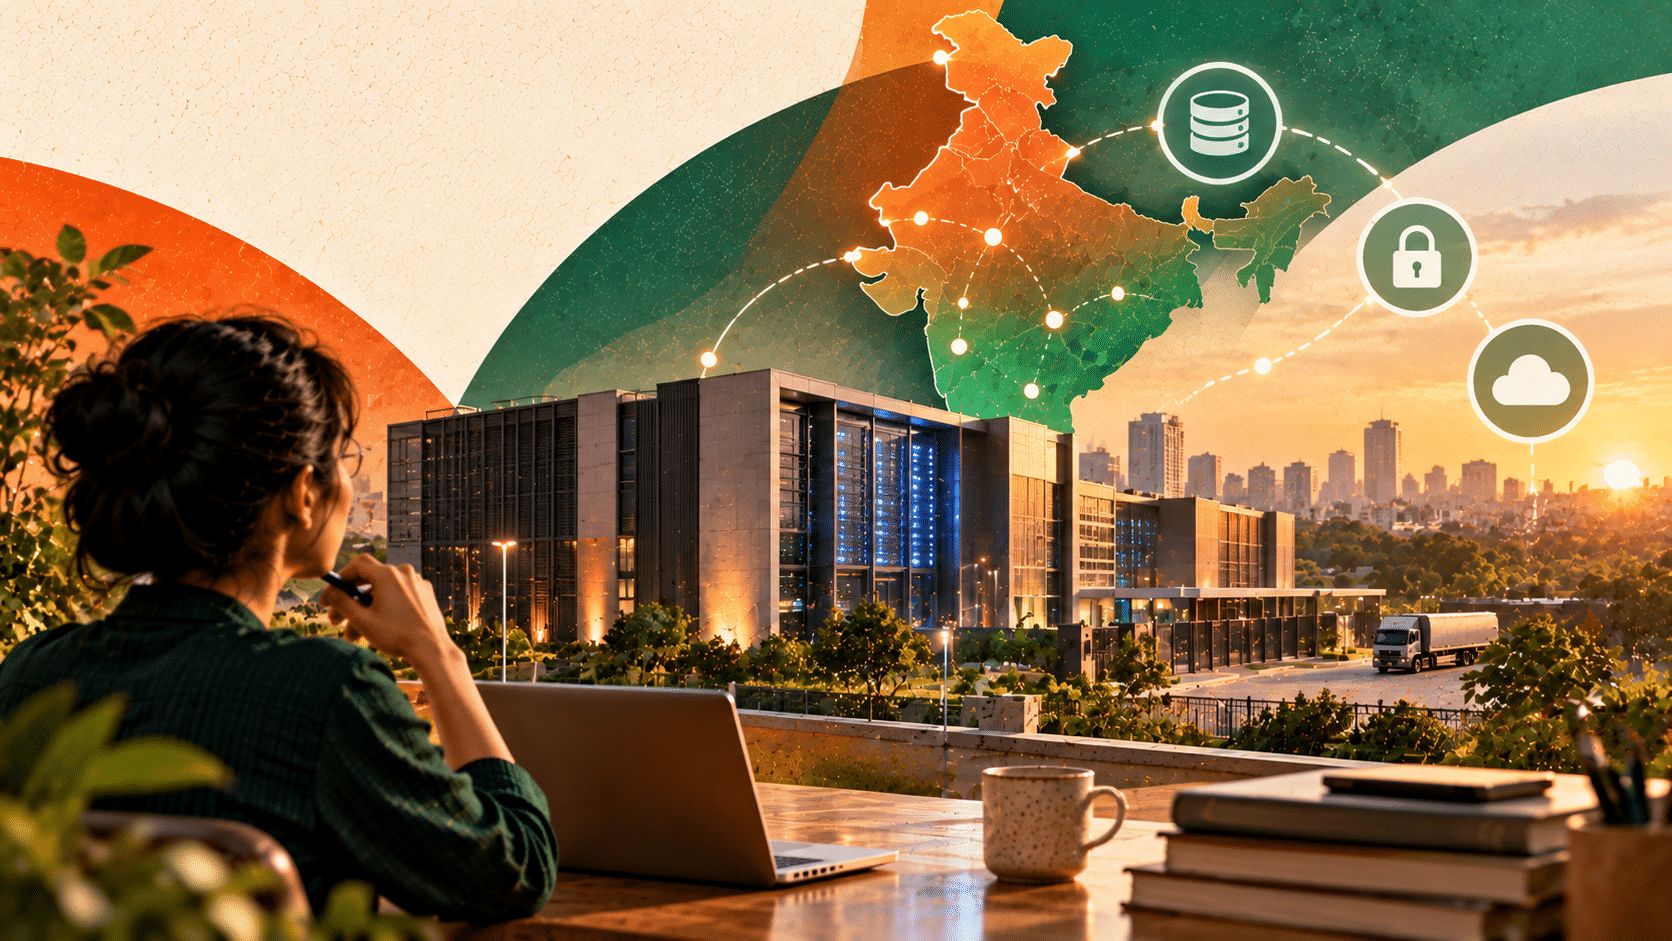
Amazon Bedrock now offers an India geographic inference profile for Claude Opus 5, Sonnet 5 and Haiku 4.5. Requests can be routed between AWS regions in Mumbai and Hyderabad while inference stays within India.
That sounds like an infrastructure update. For teams handling sensitive information, it is a much more practical change.
What changed
Previously, using a model from India did not necessarily mean its inference stayed in India. The new geographic profile gives organisations a way to keep Claude inference within the country while still drawing on capacity across two Indian AWS regions.
AWS says Amazon Bedrock does not store model inputs or outputs by default under its zero data retention model. Requests are encrypted in transit, while monitoring through CloudWatch and CloudTrail remains associated with the source region.
Do not translate “in-country” into “automatically compliant”
Data residency solves one part of a much larger governance question. Your organisation still needs to decide what information may enter an AI system, who can access the workflow, what gets logged elsewhere, which integrations receive the output and where a human must approve an action.
So instead of asking, “Can we use Claude now?”, run the workflow through this five-part check.
The five-part data-residency check
1. Identify the actual data
Write down what the workflow will send to the model. “Customer support” is too vague. Customer names, account history, uploaded documents and payment information are different data classes and may have different handling rules.
2. Map the whole route, not just the model
The model may process data in India while another tool in the workflow sends information somewhere else. Map the path from source file or application → Bedrock → Claude → output → storage → downstream apps.
3. Separate processing from storage
Ask two questions independently where is the request processed, and where is the resulting data stored? Check your own logging, application databases, observability tools and connected services rather than assuming the model setting covers them.
4. Set the human-review boundary
Local inference does not make an automated decision correct. For workflows involving money, employment, legal commitments, customer communications, regulated records or irreversible actions, define exactly where a person reviews the output before anything happens.
5. Test with the least sensitive version first
Start with synthetic, redacted or lower-risk information. Validate the workflow, permissions, logs and outputs before expanding access to sensitive production data.
A prompt to map the workflow before deployment
I am considering an AI workflow for [task]. The information involved includes [data types]. The tools connected to the workflow are [tools]. Map the complete data journey from input to final output. For every step, identify what data enters, where it may be processed or stored, who can access it, what action the AI can take, and where human approval should be mandatory. Flag any assumptions I need to verify with our IT, security, legal or compliance team. Do not treat data residency as proof of compliance.
Where this becomes useful
The immediate use cases are not necessarily flashy. Think summarising internal policy documents, extracting information from operational records, helping staff search approved knowledge bases, drafting responses from controlled source material, or supporting analysis where sending data outside the required geography was previously a blocker.
The bigger lesson is useful beyond Claude model choice is becoming an infrastructure decision as well as a capability decision. When AI moves deeper into everyday work, teams need to know not only what a model can do, but where the data goes while it does it.
Human review boundary Data residency, encryption and zero-retention settings can support a compliance strategy, but they do not determine whether a particular workflow meets your organisation’s legal, regulatory or security obligations. Verify those requirements with the responsible internal teams before using sensitive data.